REMIT starts in shadow mode: two weeks, on your own servers, with your own data, zero actions taken.See the pilot

Products · REMIT

The on-premise AI decision platform.

Four products that read, decide, check and review, and a proof record that proves each decision. Runs entirely inside your data centre.

Decide what you can prove. Defer what you cannot. Explain both.

Status. REMIT is in active development. The first solution, banking complaints and alerts, is being built and benchmarked on public regulator data; design-partner deployments run as forward-deployed engagements. Nothing here reports a production deployment.

DocumentsProof
  1. FOLIO

    Reads the documents

  2. SIFT

    Decides the clear cases

  3. BOUNDS

    Knows when to stop

  4. BENCH

    Puts a person on the rest

The four products

Each one does a job you can name.

01

FOLIO

Reads the documents

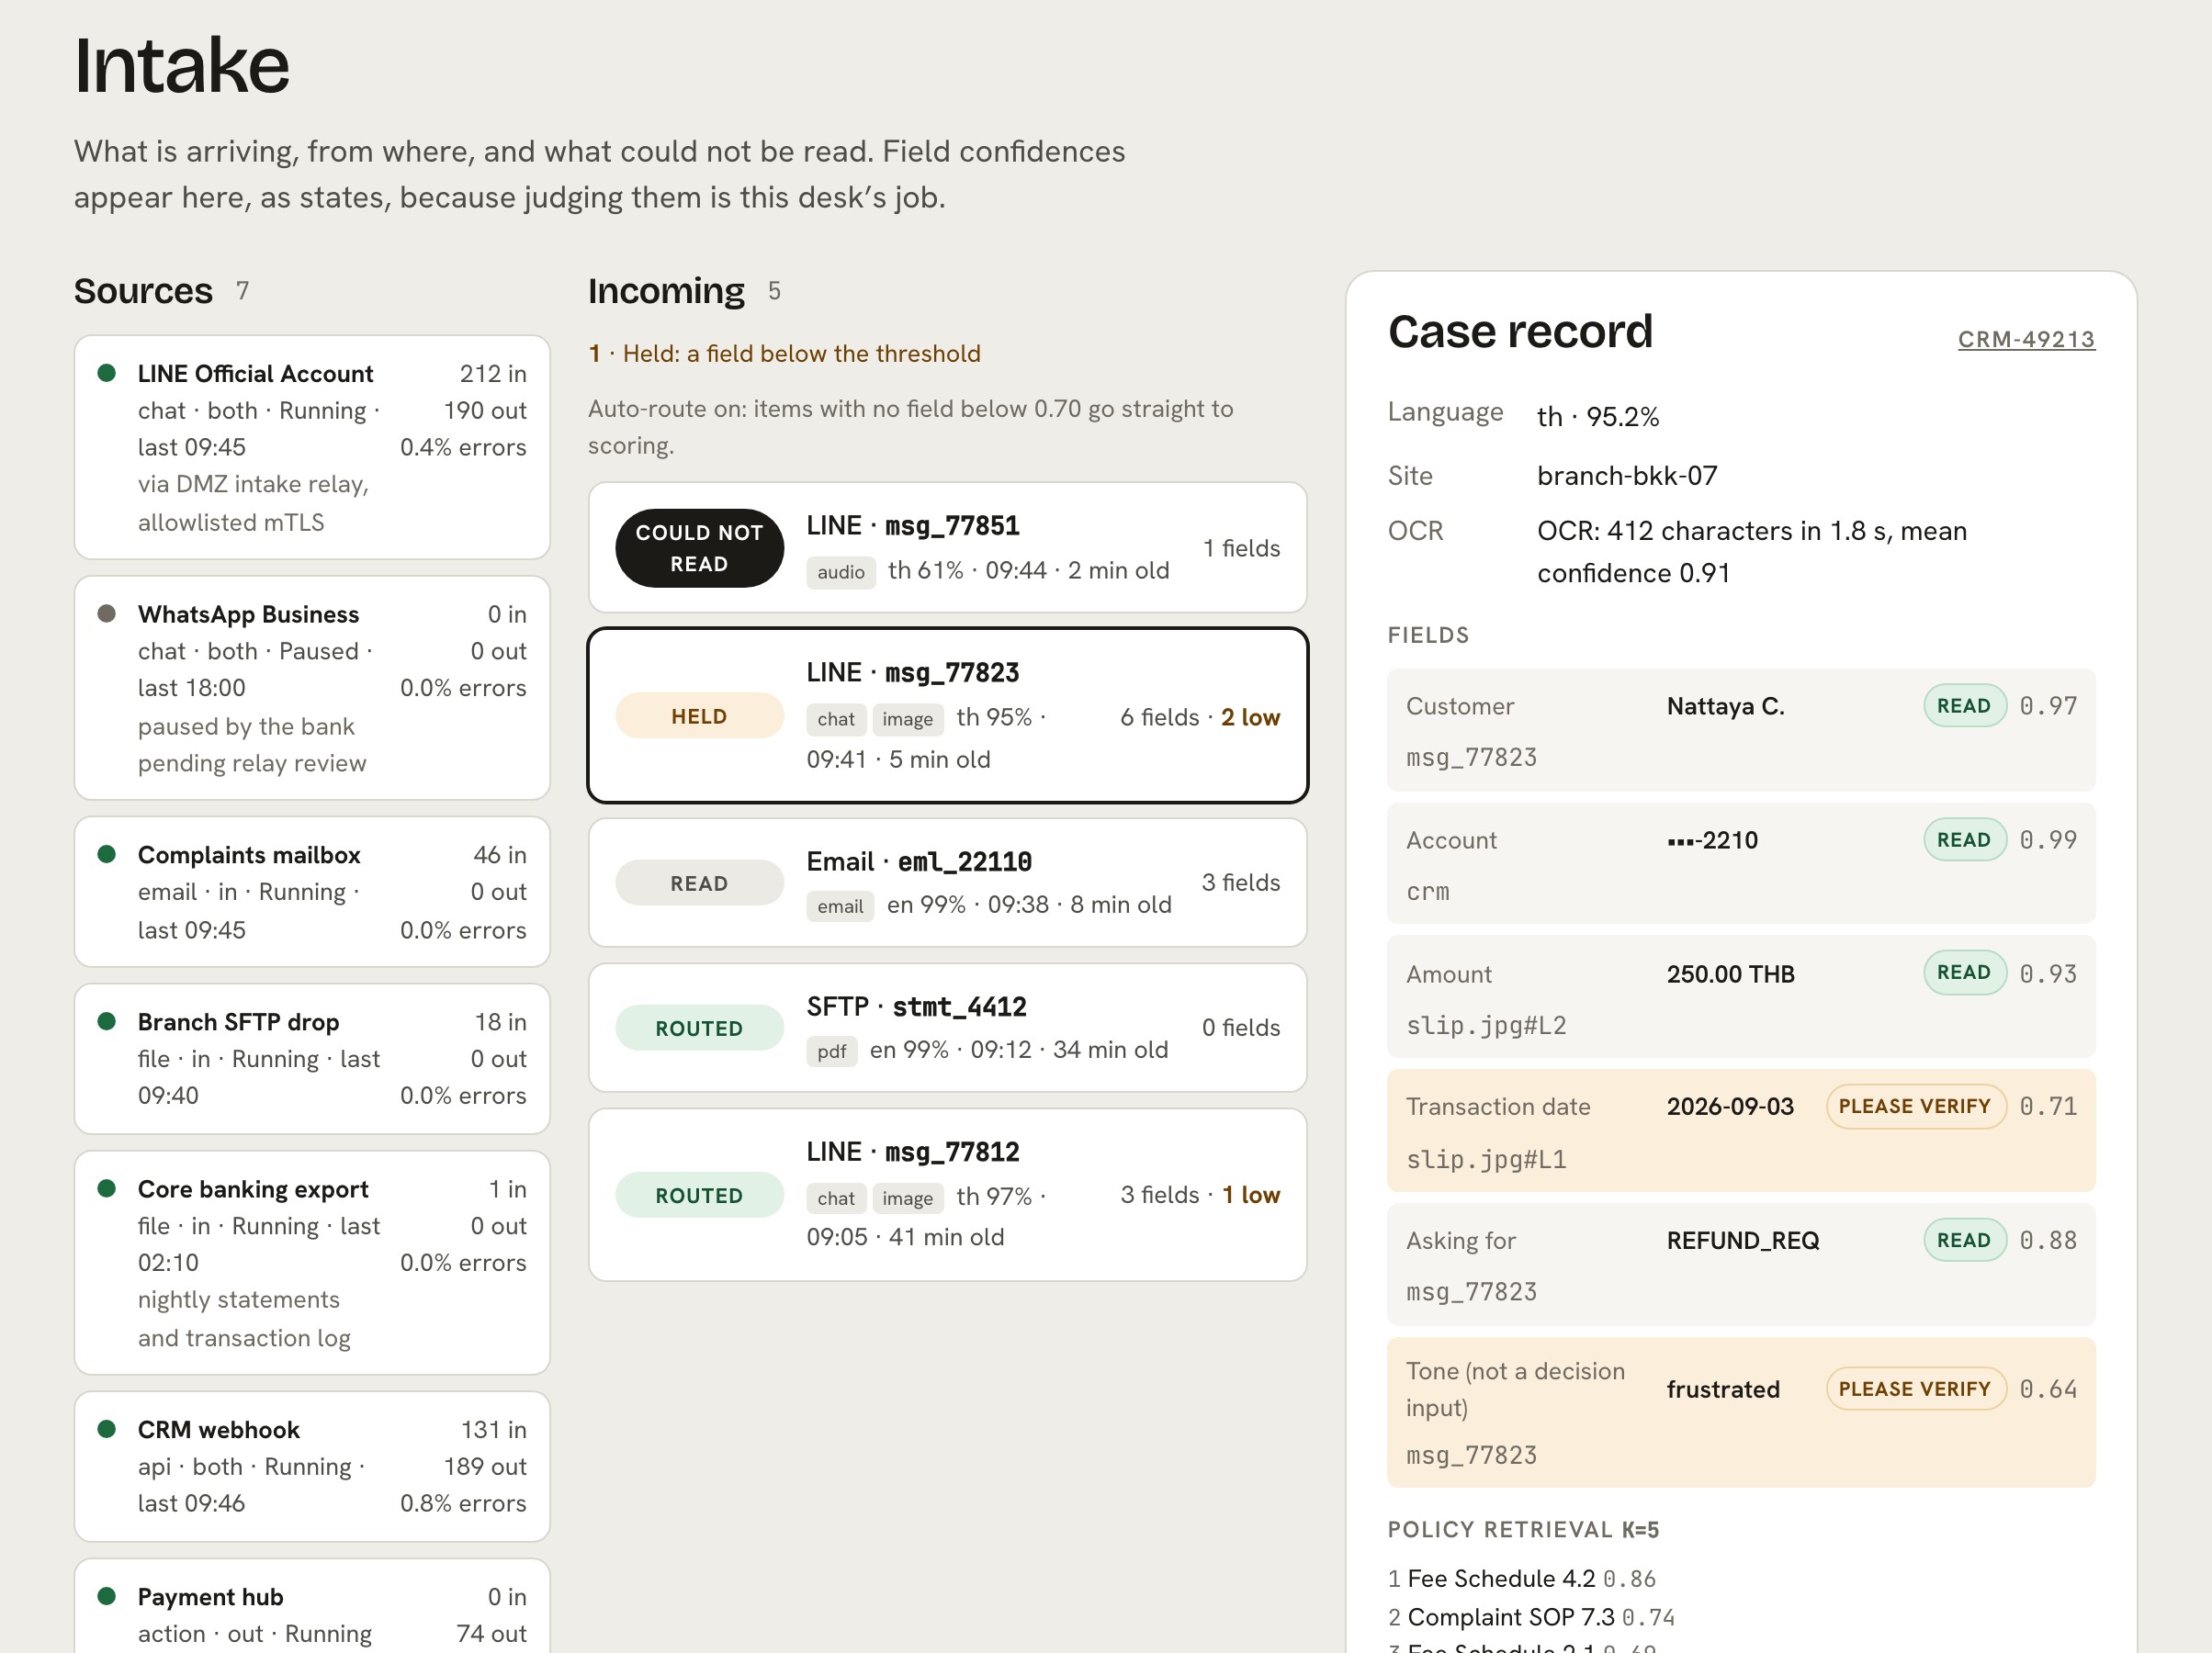
Messages, voice notes, slips, claims, statements and policies become one case record, every field traced to the line it came from.

  • Thai, Bahasa, Malay, Vietnamese, Tagalog and English inputs
  • Every fact cited to its source document
  • Connects to your channels and core systems
Product demonstrator · illustrative case data
The FOLIO intake screen: sources, incoming documents, and the case record with each field marked read or please verify.
02

SIFT

Decides the clear cases

A small model trained on your workflow chooses from your list of outcomes. It cannot invent an option and it cannot write free text.

  • Outcomes agreed with your domain experts
  • Same input, same answer, every time
  • Seconds per case, on a branch-class machine

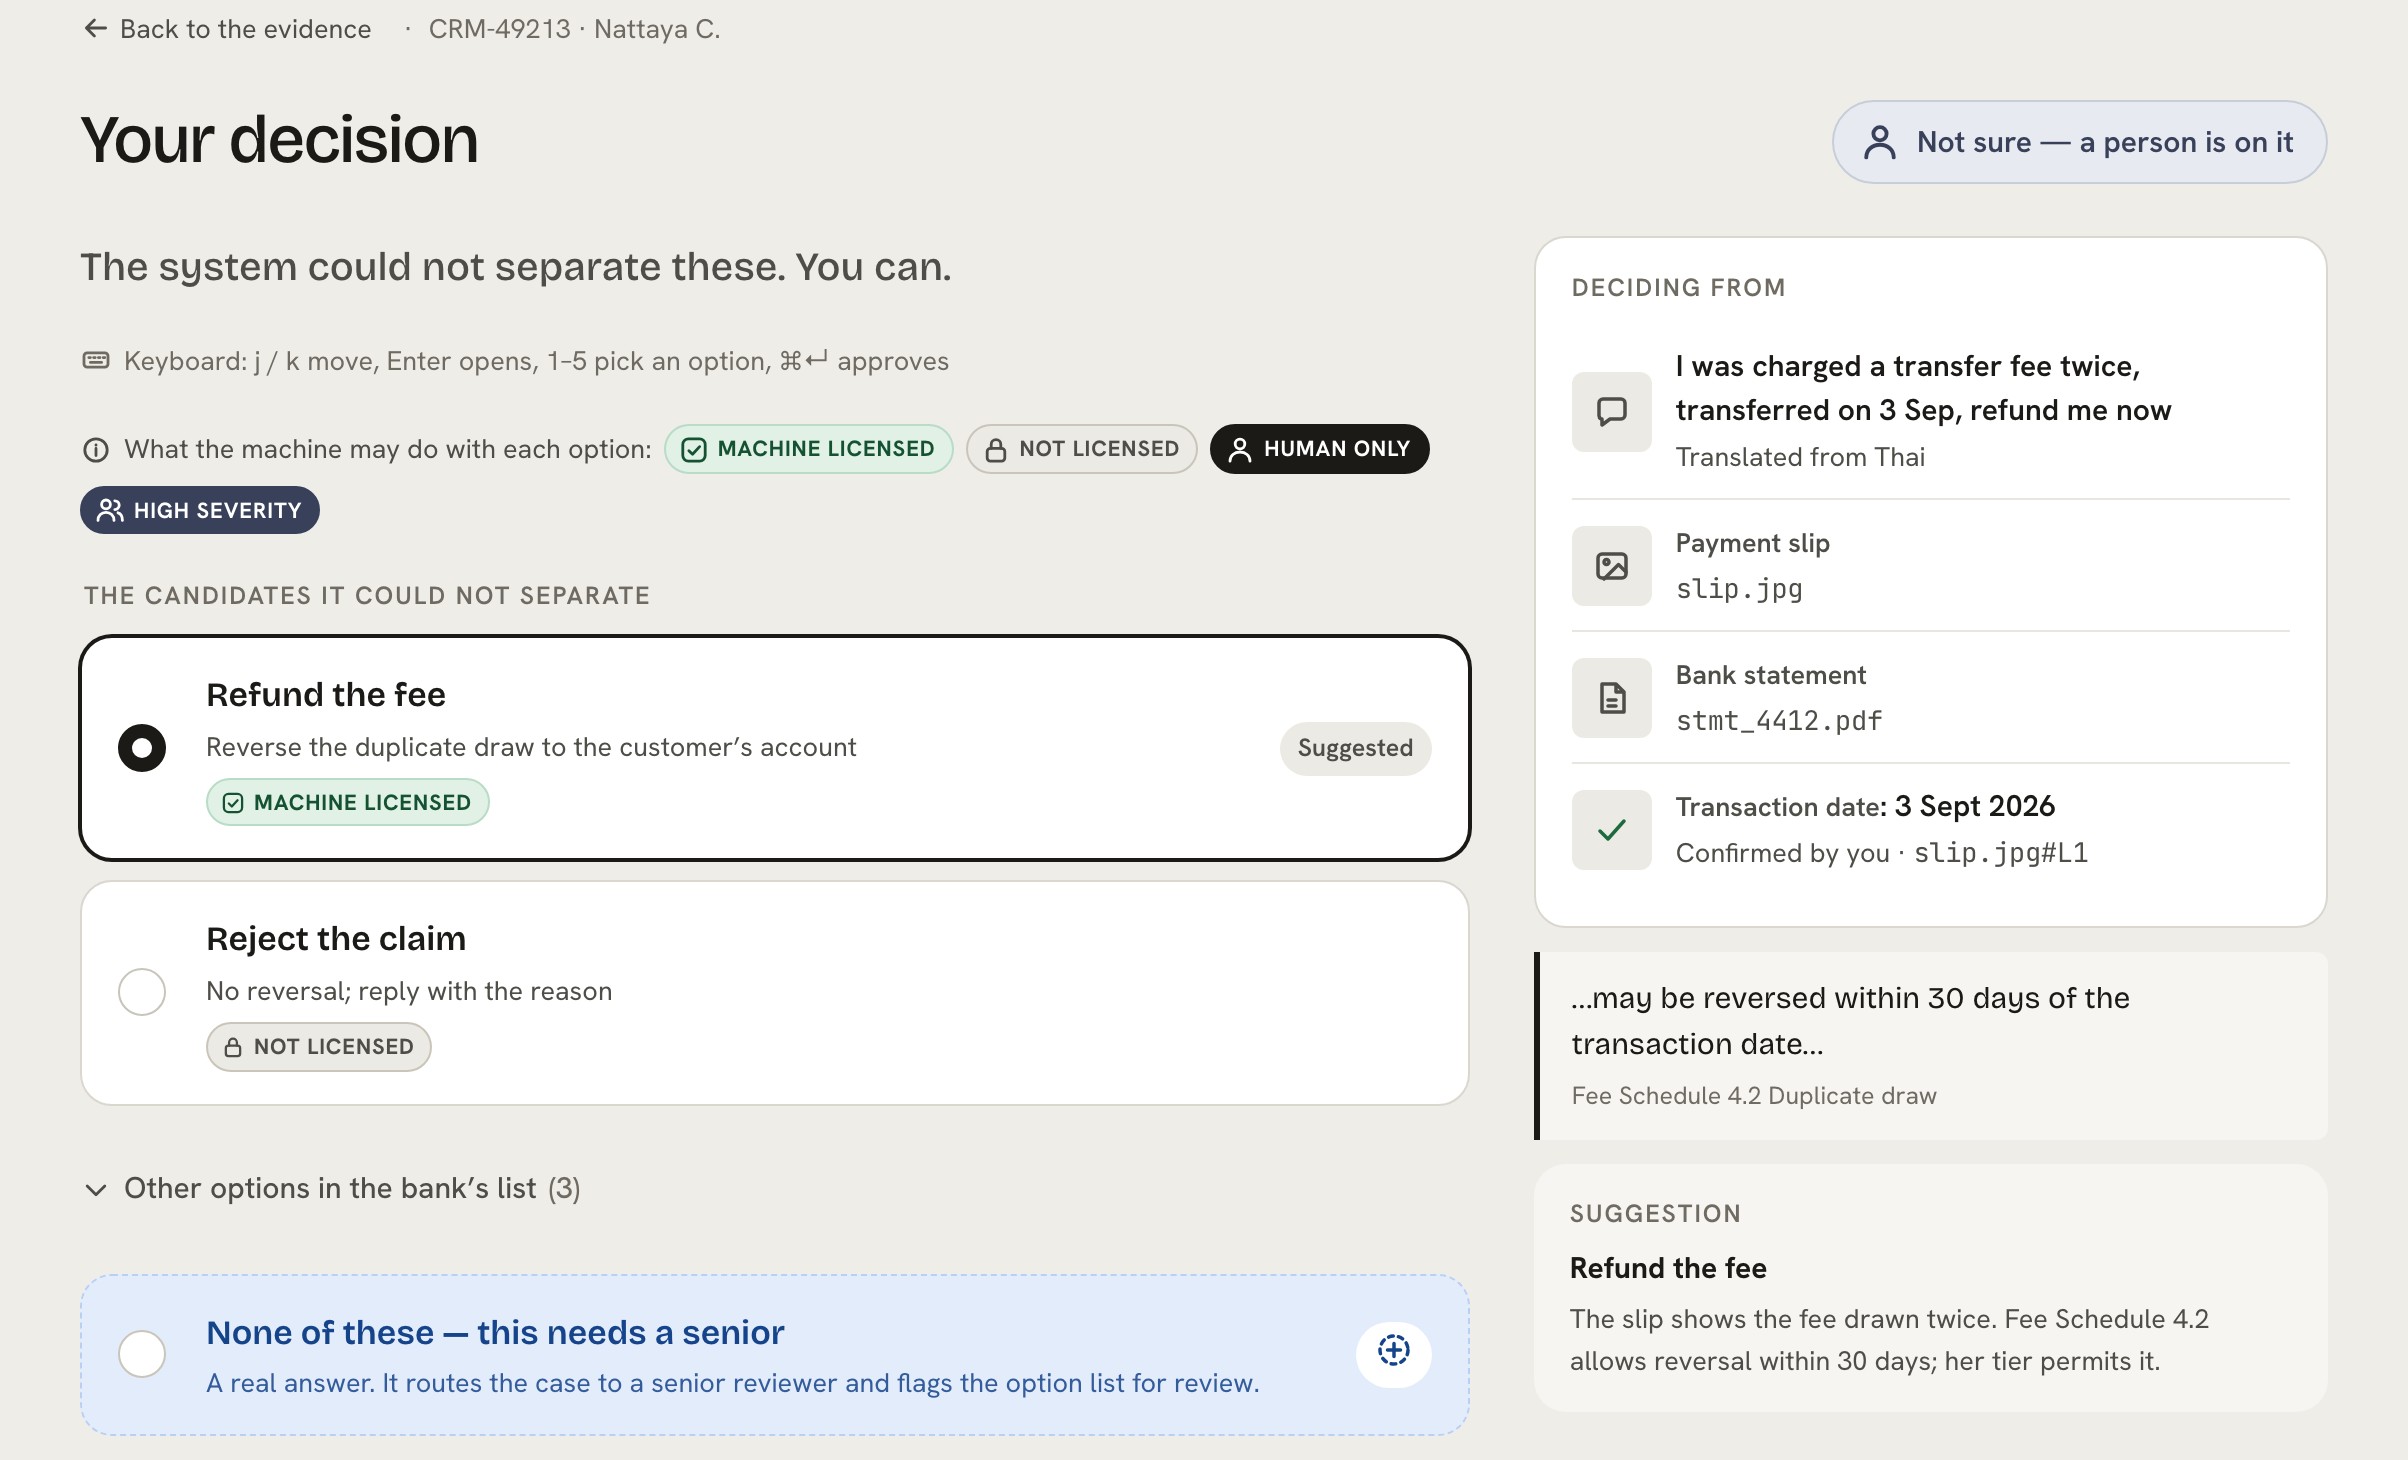
Your list of outcomes

  • Refund the fee Chosen
  • Goodwill credit instead
  • Ask for the transaction reference
  • Reject the claim
  • Escalate to fraud

Same input, same answer. Nothing outside the list.

03

BOUNDS

Knows when to stop

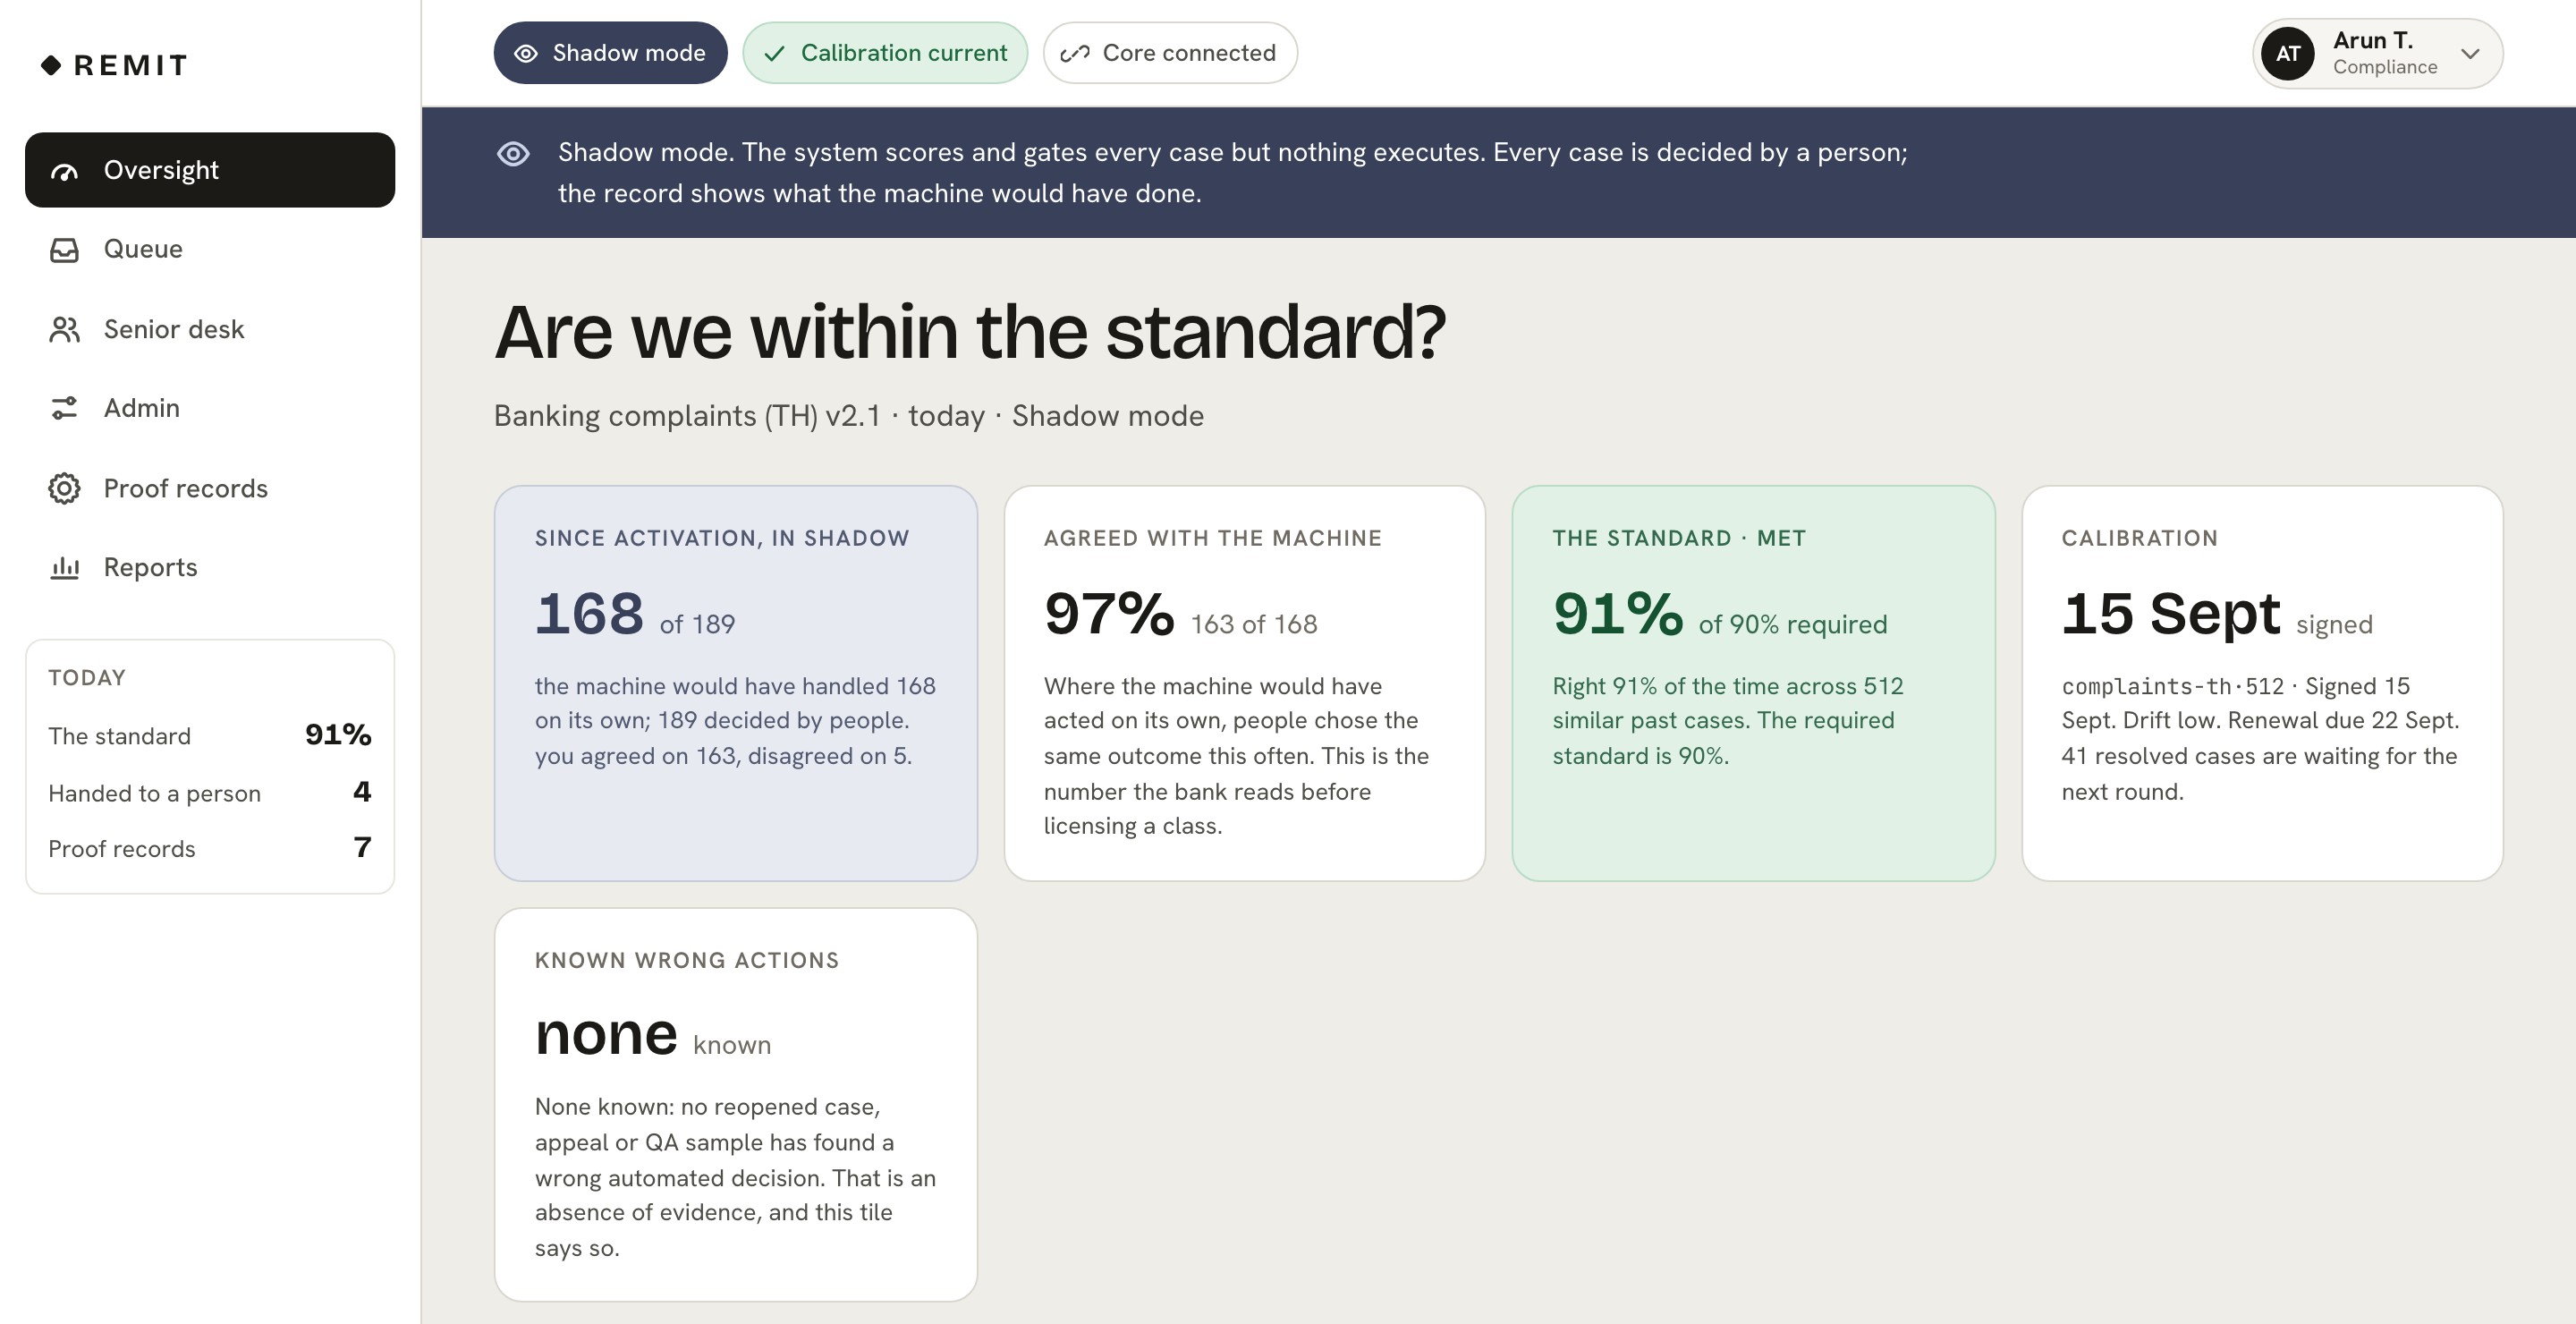
Measures, against a standard set on your own past cases, whether the system is sure enough to act. If not, it hands the case to a person. This is the core of REMIT.

  • An accuracy standard you set, measured before go-live
  • Stops on two plausible outcomes or anything unfamiliar
  • Re-measured on a schedule; stale means everything goes to people
Product demonstrator · illustrative case data
The BOUNDS oversight screen: are we within the standard, agreement with the machine in shadow mode, calibration date, known wrong actions.
04

BENCH

Puts a person on the rest

Your reviewers see the evidence first, a suggestion clearly marked as a suggestion, and the same list of outcomes. They decide; the trail records it.

  • Evidence, policy passages and what would settle the case
  • Queues, due times and a senior desk for the unfamiliar
  • Approve and record in one step
Product demonstrator · illustrative case data
The BENCH decision screen: the two candidates the machine could not separate, which options the machine is licensed to act on, and the reviewer’s note.

On every decision

The proof record

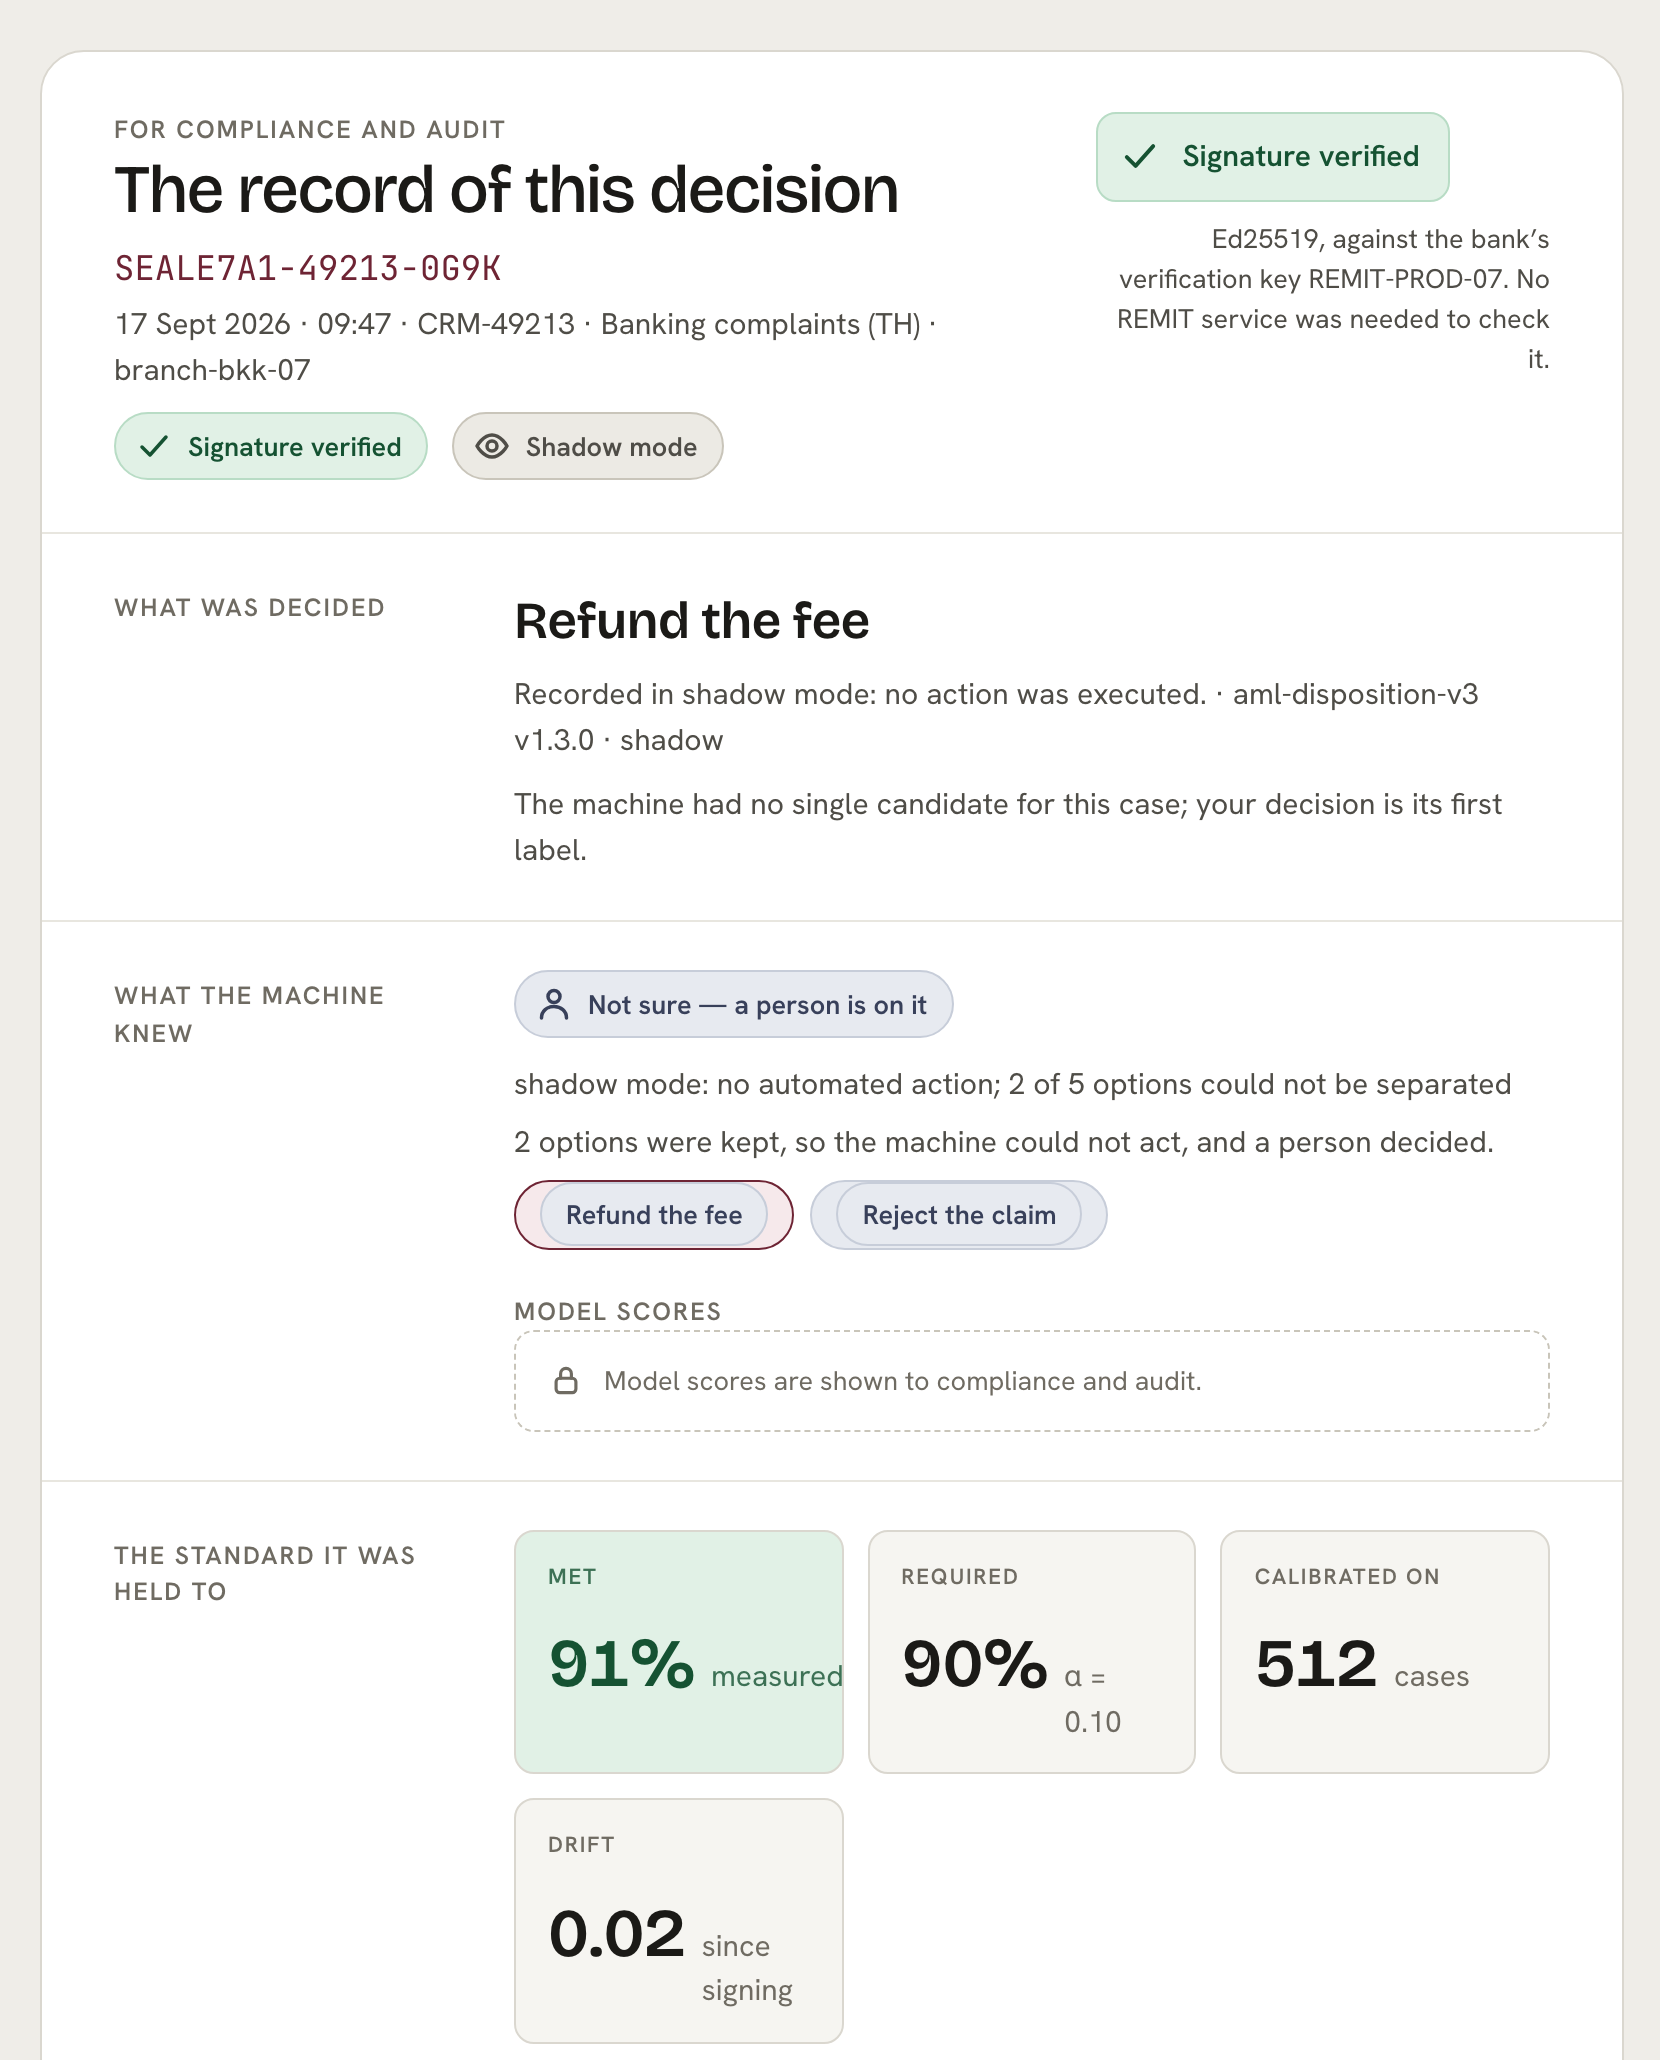
A signed record of what was read, what was decided, by whom, and against which standard. A regulator can verify it with your public key, without us in the room.

What a proof record contains

  • The case and the documents read
  • The outcome chosen, and the alternatives kept open
  • Who approved it, with their note
  • The accuracy standard in force and its measurement
  • The policy passages relied on
  • A signature you can verify offline

Verifiable without us.

Records are append-only in your own audit store and export as JSON or PDF. The public key and the record are enough.

Product demonstrator · illustrative case data
A proof record: signature verified against the bank’s key, what was decided, what the machine knew, and the standard it was held to.

Sector solutions

One platform. Adapted per workflow.

Each sector solution adds your documents, your list of outcomes, an accuracy standard measured on your past cases, and a compliance package for your regime. The platform underneath never changes.

Not tied to one model.

The standard is measured, not assumed, so the underlying model can change and the proof survives.

Improves with use.

Every case a person resolves becomes a labelled example for the next measurement round.

Labels carry provenance.

The record says which examples came from people and which did not, so an auditor can weigh them.

For model-risk and audit teams

The guarantee, stated precisely

BOUNDS uses split-conformal prediction over the workflow’s option set. Given n calibration cases held out from training, it emits a prediction set that contains the true option with probability at least 1 − α, for any model and any data distribution. The assumption is exchangeability between the calibration set and live cases; under drift the bound is void, so drift monitors and a scheduled re-calibration are part of the product, and a stale calibration routes every case to a person. Coverage is a frequency over cases, not a per-case promise.

The evidence base, with citations

What we don’t charge for

  • Tokens. Never. No metering on usage.

  • The base models. Open weights. You own the right to run them.

  • Hand-offs to people. Stopping when unsure is the product, not an overage.

  • Your data leaving your walls. Because it doesn’t.

A decision queue you cannot put in the cloud?

That is what REMIT is built for. The first paid step is small.